- Internal
- MLOps
AutoLLama
One command to build, configure, and launch local LLM inference
Build and deployment toolkit that compiles llama.cpp with the right GPU flags and launches inference services (LLM, embeddings, reranker) across local or distributed workers. Includes TUI dashboards for build profiles and subnet scanning to discover RPC workers.
- Python
- llama.cpp
- CUDA
- CMake
- Curses TUI
- Transformers
- RPC
- LiteLLM
From hardware profile to a running inference endpoint
AutoLLama converts build flags, model choice, local hardware, and optional RPC workers into a reproducible llama.cpp or reranker launch instead of a fragile sequence of manual commands.
The operator selects workload, model, and acceleration
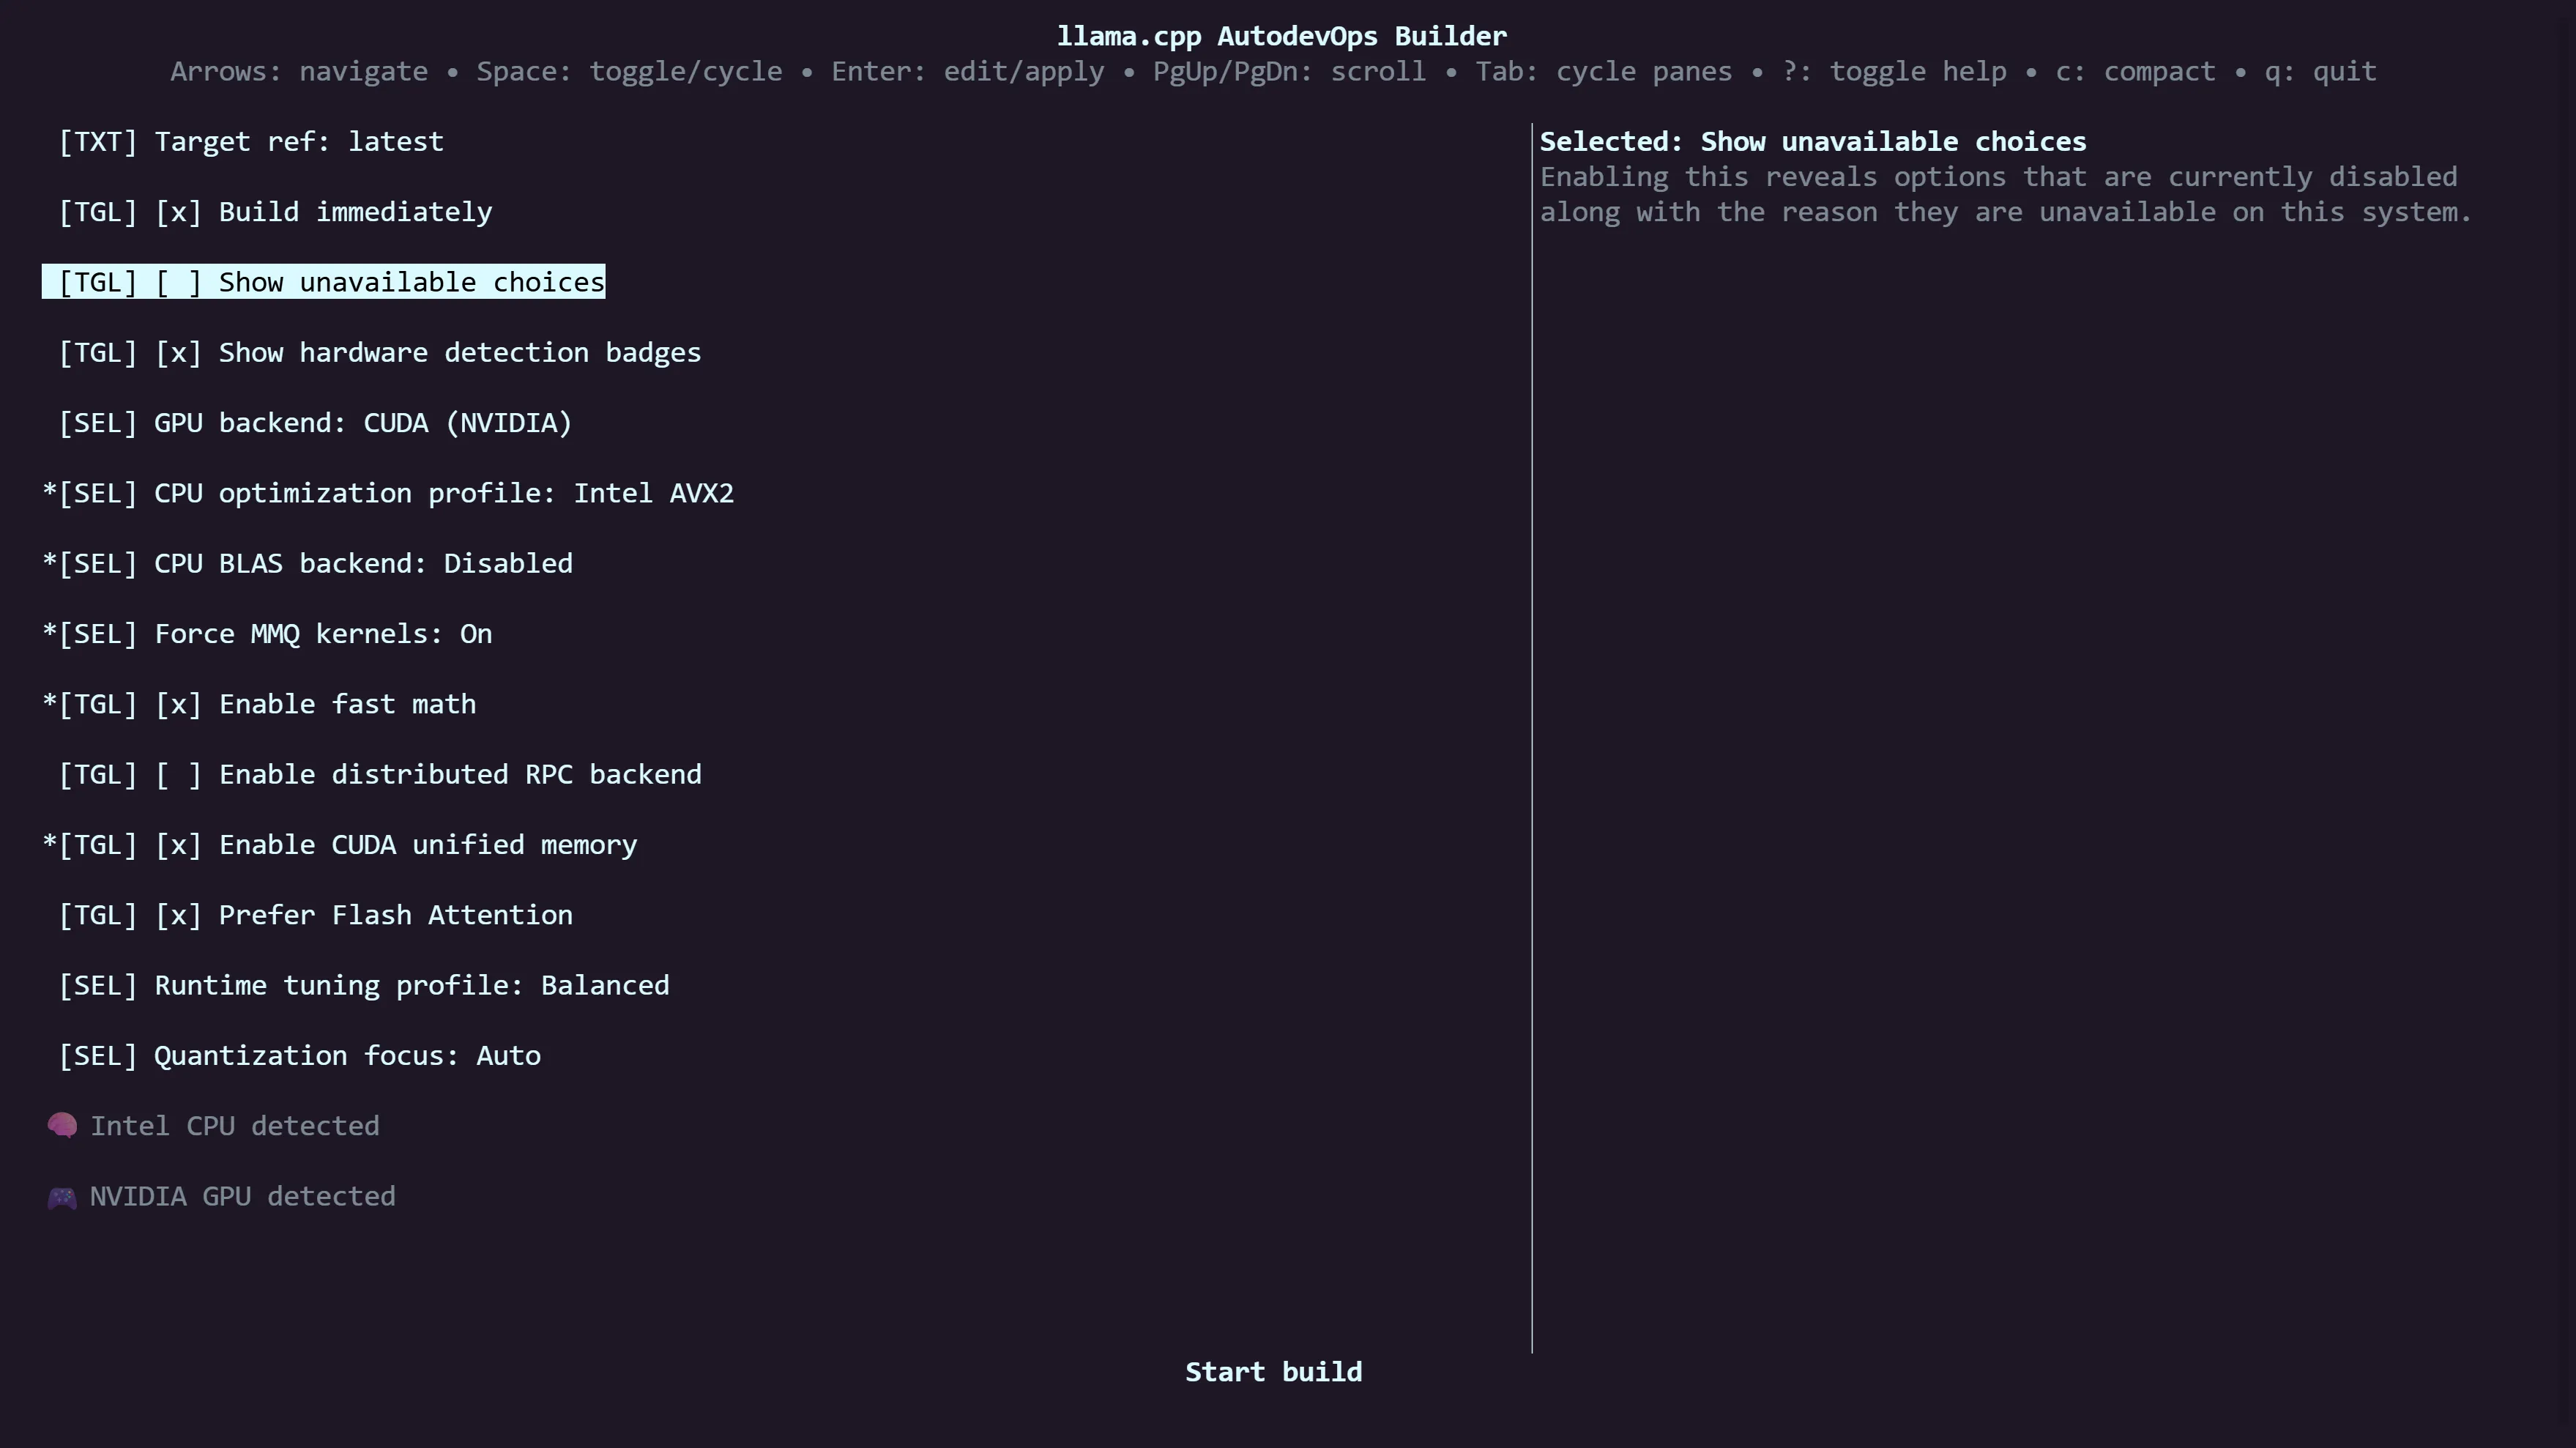
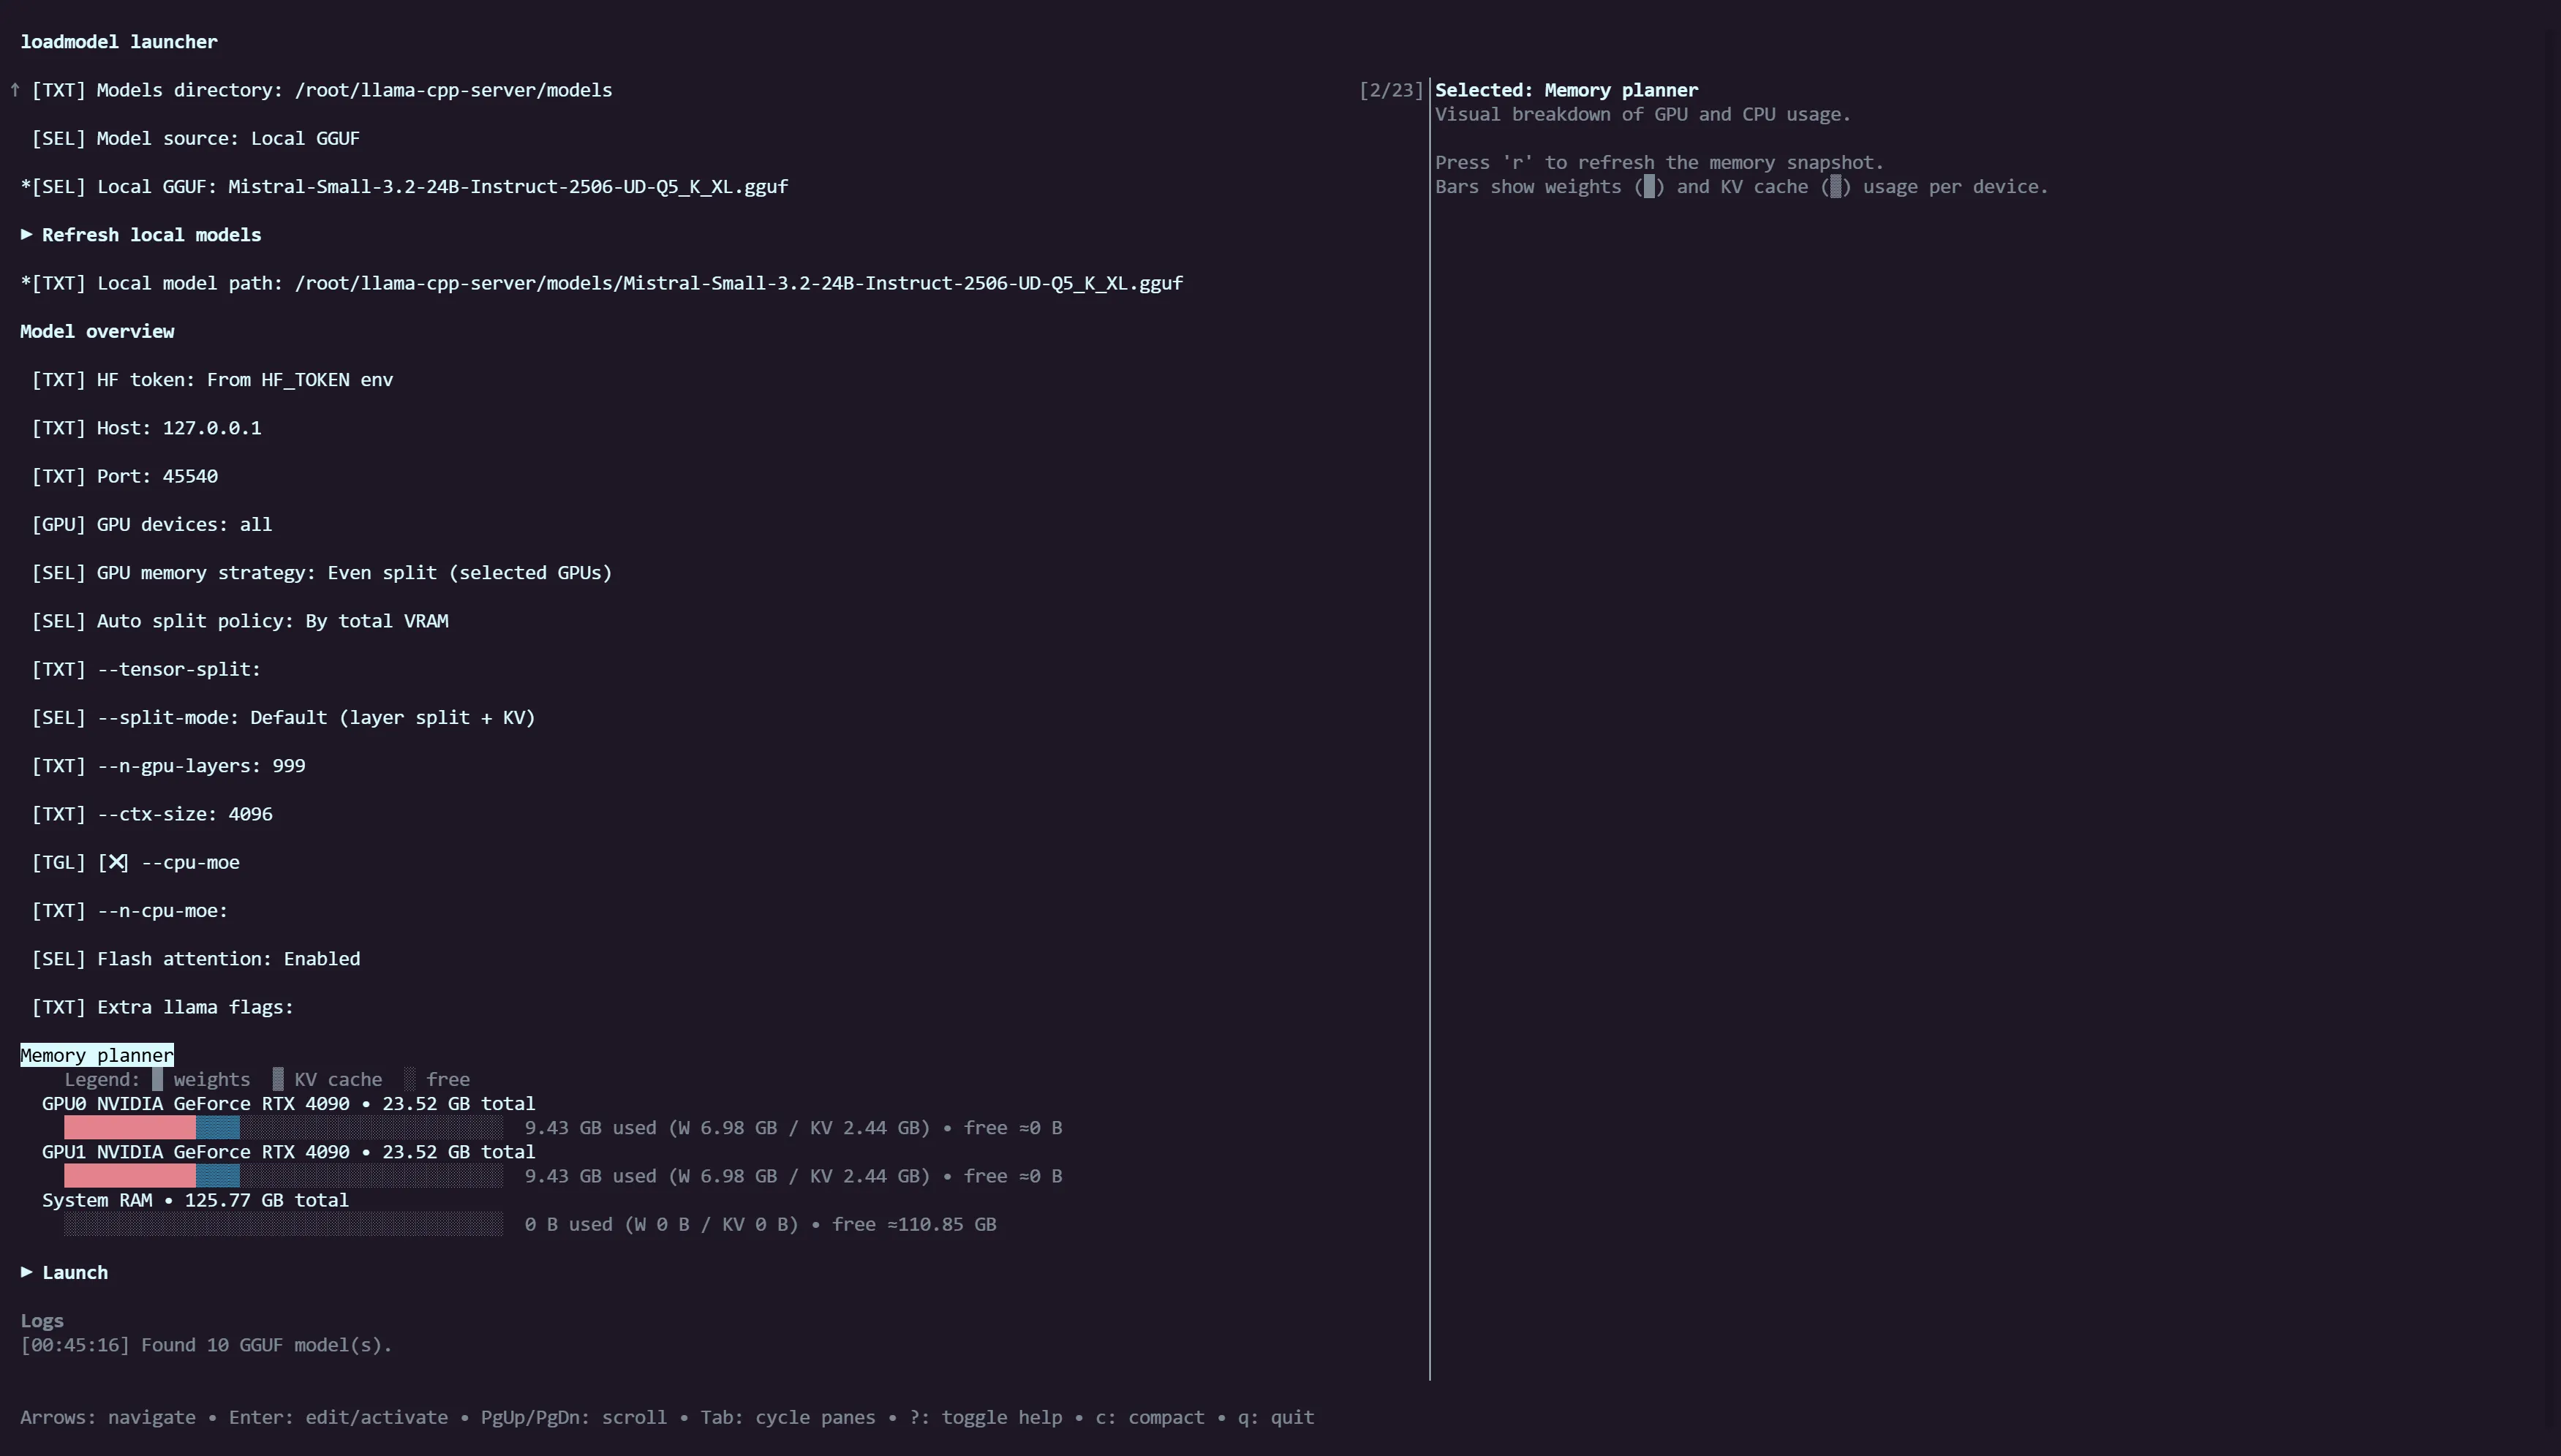
A CLI or curses TUI captures the llama.cpp ref, local GGUF or Hugging Face target, service mode, ports, memory constraints, and CUDA, MMQ, BLAS, or RPC options.
A validated build and launch profile that can be repeated.
llama.cpp is compiled for the selected machine
The build workflow checks out the requested source and translates the profile into CMake flags for CUDA or CPU acceleration, optional fast paths, and distributed RPC binaries.
Matching llama-server, llama-cli, and optional rpc-server binaries.
Optional workers are found and assembled safely
Subnet scanning discovers compatible RPC workers and their advertised endpoints. The launcher builds an explicit worker list rather than assuming every device or address is available.
A concrete local or distributed inference topology.
The correct inference service starts with visible configuration
AutoLLama launches llama-server for generation or embeddings, a Transformers HTTP service for reranking, or llama-cli with RPC workers, using known ports and the chosen memory/runtime settings.
A reproducible LLM, embedding, or reranker endpoint ready for clients.
Build targets
- CUDA
- GPU builds with optional MMQ fast paths
- BLAS (MKL/OpenBLAS)
- CPU acceleration options for non-CUDA runs
- Distributed RPC
- Builds rpc-server and enables multi-worker inference
Features
- Build automation for llama.cpp (ref selection + flags)
- Curses TUIs for build and launch workflows
- Run llama-server for LLM + embeddings
- Run Transformers reranker HTTP service
- Distributed inference: scan subnets for RPC workers + launch llama-cli with --rpc
- Unit tests for build/config logic
Production notes
- Own inference deployment
- Serves my four-RTX-4090 cluster behind LiteLLM. With MTP speculative decoding, Qwen3.6-35B-A3B reached 171 tokens per second in this setup; throughput depends on the model and workload.